Tesla’s shadow mode demonstrates that the true value of a data asset lies in a continuous loop of generation, use, feedback, and correction rather than static storage. Two years ago, when the first provisional provisions on accounting treatment for enterprise data resources were implemented, the corporate world was primarily focused on how to record digital information as a financial asset on a balance sheet. The conversation revolved around valuation figures—hundreds of millions of dollars seemingly locked in databases. However, by 2026, the industry has experienced a profound shift in perspective. Major content licensing agreements, such as those signed by Reddit and News Corp with prominent artificial intelligence developers, have proven that the real value of data is not found in a static database copy, but in the training rights that allow models to learn from it. This transition from accounting value to utility value marks the beginning of a new era where data is treated more like a living organism that feeds intelligence systems rather than a dormant piece of real estate.
1. Shift in Pricing Authority: From Financial Exchanges to Server Rooms
Traditionally, the pricing of data assets relied on three distinct reference points: the listing prices on formal data exchanges, intangible asset appraisal standards, and accounting caliber for financial statements. This system was built on the fundamental assumption that data possesses a fixed “fair value” similar to physical land or commercial property. However, the rise of large-scale generative models has completely overturned this premise. Today, the most aggressive buyers of data are no longer brokers or traditional analytics firms, but large-scale model training facilities. Their logic for acquisition is entirely different from the old guard; they are indifferent to the total size of a dataset in terabytes and are instead focused on how much that information can enhance a model’s specific capabilities. A collection of customer service logs might be worth very little under a traditional cost-based appraisal, yet for a developer building an intelligent agent, those same logs represent invaluable training samples packed with real-world human feedback.
The mechanism driving this change is the radical shift in the marginal value curve of data. In the previous technological cycle, the primary consumers of data were humans, whose reading and comprehension capacity had a natural upper limit. In contrast, the consumers of data are now models, and their appetite for training corpora is measured in trillions of tokens. This massive increase in demand shifts the entire economic curve, causing the price of scarce, high-quality, and semantically clear data to rise steadily. Consequently, the actual worth of an enterprise’s data now depends less on how well an appraisal report is drafted and more on the number of AI developers who need that specific information to refine their systems. True valuation is no longer a matter of bookkeeping; it is a matter of how effectively that data can “feed” the next generation of intelligence, moving pricing authority away from financial auditors and into the hands of those managing GPU-heavy server environments.
2. The Primary Consumer Shift: From Humans to Machines
For decades, the design of data catalogs, dashboards, and indicator systems was centered around human readability. Engineers and analysts meticulously crafted visualizations and reports to cater to the cognitive habits of management teams and business users. However, in the current landscape, a new type of reader has become the dominant force: the AI Agent. These autonomous entities—whether they are procurement agents reading material masters to place orders or financial agents reconciling accounts—consume data at a volume and speed that humans cannot match. These machine readers do not care about the aesthetic appeal of a polished dashboard or the narrative flow of a report. Their requirements are purely functional, focusing on the underlying structure and the precision of the metadata that enables automatic invocation.
The preferences of these machine readers differ fundamentally from those of their human predecessors. While humans can use intuition and tacit understanding to navigate ambiguities, machines will execute an ambiguous instruction to its literal, and often incorrect, end. For example, where a human recognizes that two slightly different part codes refer to the same physical bearing, a machine reader may interpret them as unique materials and trigger an unnecessary procurement order. This shift has necessitated a new standard for data asset availability known as “machine readability.” To be valuable in 2026, data must be structured without ambiguity, and its metadata must be complete enough to support automated calls without human intervention. Enterprises are now prioritizing the creation of API catalogs designed for machine consumption over traditional web-based interfaces meant for human browsing, recognizing that those who facilitate machine access will see their AI systems perform more effectively.
3. New Quality Benchmarks: From Auditable to AI-Ready
In the past, the success of a data governance project was measured by its compliance with audit traces, data accuracy rates, and standard coverage. While these metrics remain necessary for regulatory purposes, they are no longer sufficient to determine the utility of a data asset. The critical question today is whether an organization dares to feed its data directly into a model without manual oversight. There is often a significant gap between data that is “audit-compliant” and data that is “AI-ready.” Many organizations have discovered that even if their master data passed traditional accuracy checks, it failed to perform in Retrieval-Augmented Generation scenarios because the information relied on internal context or informal understandings that the model could not grasp.
This realization has led to the emergence of new industry metrics focused on the direct utility of data for artificial intelligence. One such metric is the “corpus conversion rate,” which measures the proportion of structured data that can be used for training or retrieval without secondary cleaning. Another is “semantic density,” which evaluates whether the annotations and business meanings are comprehensive enough for a machine to understand the data independently. Furthermore, organizations are now documenting their “ambiguity inventory,” a list of business calibers that are traditionally understood only by veteran employees through experience. Because an AI Agent will guess an answer rather than ask for clarification when it encounters a conflict, these ambiguities have become major operational risks. Modern data governance now focuses on ensuring that the model is never less reasonable than the data it consumes, as governance debt now directly limits the quality of AI output.
4. The Rise of Three New Valuation Accounts
The integration of artificial intelligence into core business processes has introduced three distinct types of data accounts that were previously non-existent. The first is the external licensing account, which handles the rights associated with data scraped or provided for model training. As global markets establish clearer pricing for these assets, enterprises must inventory their data to determine which portions possess high licensing value and ensure that their contracts specifically address AI training rights. The second is the reflux data account, which tracks the high-quality information generated through model outputs and user interactions. This data is particularly valuable because it contains direct business feedback and corrections. Determining who owns this reflux data and how it is governed has become a central challenge for asset management, as static inventories can no longer keep pace with the rapid proliferation of information in an active AI flywheel.
The third emerging account is dedicated to synthetic data. As models increasingly rely on data they have generated themselves to fill gaps in training sets, questions regarding the reliability and value of this synthetic information have moved to the forefront. Most legacy asset management systems do not even have a category for synthetic data, yet it now supports a significant portion of training corpora in specialized scenarios. These three accounts represent a fundamental shift in the boundary of data assets, moving from a stock-based perspective to a flow-based one. In the current environment, data assets are no longer viewed as static snapshots in a ledger but as dynamic, feedback-driven loops. Snapshot-style management is increasingly viewed as obsolete because it misses the fastest-growing and most high-velocity segments of an organization’s digital wealth.
5. The Superior Asset Form: From Data Pools to Data Flywheels
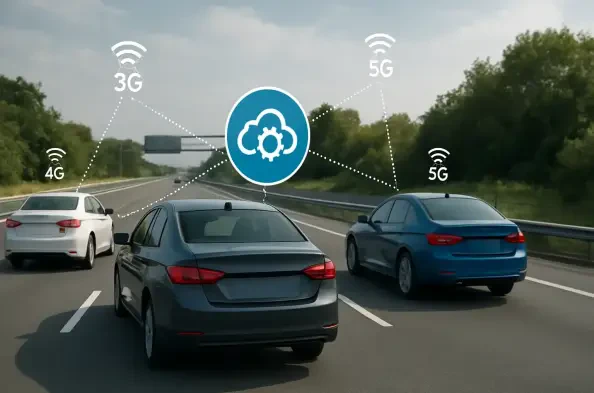
A comparison between stagnant data lakes and active data flywheels reveals why some organizations are pulling ahead in the intelligence race. Millions of vehicles on the road today are constantly uploading driving data that trains navigation and autonomy models, which in turn improves the product and drives more sales. This creates a continuous cycle where data value is generated through use rather than storage. In contrast, many enterprises continue to maintain massive data lakes filled with information that has not been accessed or updated in years. Without labeling or business semantics, this stagnant data quickly becomes unusable, or “silt,” when AI applications are finally deployed. The difference between these two states is the difference between a depreciating asset and a compounding one.
To evaluate data assets in this new context, a three-factor formula has become the industry standard: Data Asset Value equals Data Stock multiplied by Flow Speed multiplied by the Number of Feedback Closed Loops. While the stock provides the baseline, the speed at which data moves through the organization and the frequency of feedback loops act as the true multipliers. Two organizations may possess the same volume of data, but the one that consumes its data through models and agents every week—refining that data through constant use—will see its asset value grow exponentially. Data that remains stationary only depreciates as business contexts change and old calibers drift. Therefore, the highest value form of a data asset in 2026 is no longer the data pool, but the data flywheel that forces quality through constant application and correction.
6. Modern Strategic Framework: The Actionable Path Forward
The transition toward utility-based data valuation was completed when the industry realized that dormant information is a liability rather than an asset. To capitalize on this shift, organizations followed a specific set of strategic steps to align their governance with AI requirements. First, they conducted a comprehensive re-evaluation of their inventories using an “AI Usability Rating” that scored assets on their structural integrity and semantic clarity. This allowed them to identify which data sets were truly fit for model training. Second, they moved away from the impractical goal of full-volume governance, instead focusing their resources on specific data domains required for their most high-value AI projects. This targeted approach ensured that governance investment followed the needs of the models rather than a generic checklist.
Furthermore, legal and operational frameworks were updated to include corpus licensing and the management of reflux data. Organizations began building machine-readable data directories that prioritized API access over human-centric reporting, ensuring that AI Agents could navigate information independently. A critical part of this process involved mapping “ambiguity inventories” to convert the tacit knowledge of senior employees into explicit rules that machines could follow. Finally, reporting structures for leadership were modernized to focus on the tangible outcomes of data use, such as the number of autonomous decisions executed or the volume of person-days saved. By moving the focus from balance sheet valuations to active performance metrics, these organizations ensured that their data assets were recognized not just as numbers in a ledger, but as the essential ammunition driving the intelligence era forward.